
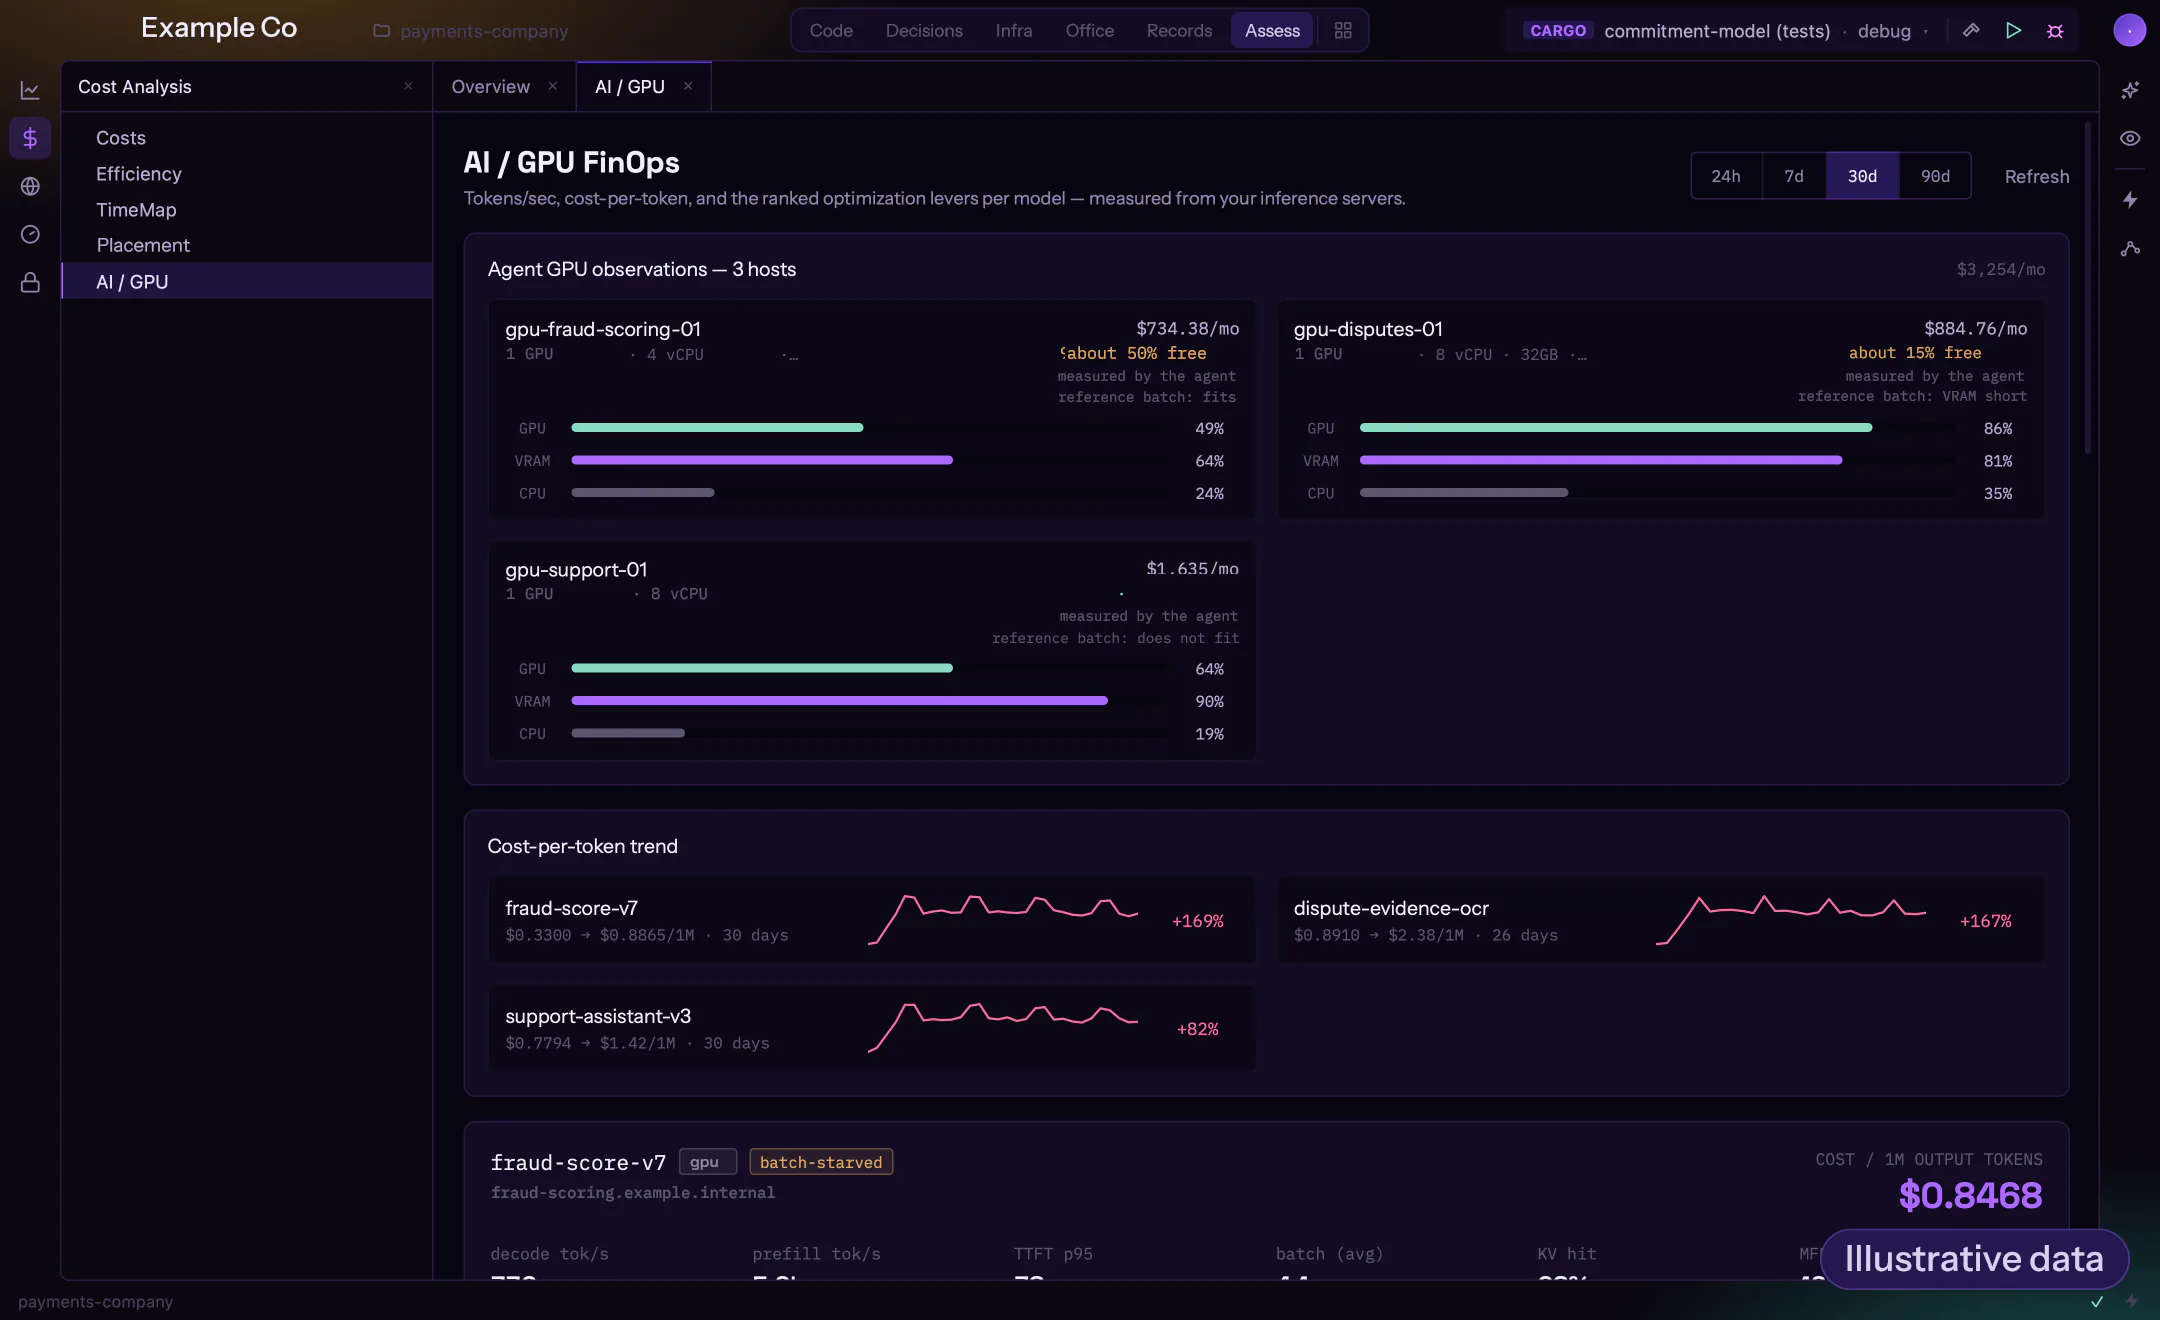
Know what you serve before you buy more
GPU capacity is bought on peak fear and billed around the clock; utilization is a guess and the cost of a million tokens is nobody's number. Inference routes to whatever was configured first.
Flex Axion measures the fleet directly: utilization per node, cost per token and per request by model, tenant and endpoint, then backtests demand and quotes where each workload runs cheapest, on GPU, ARM or x86.
What you get
- Cost per million tokens, per request and per tenant, reconciled with the bill.
- GPU fleet capacity and headroom, with the idle nodes priced.
- A backtested demand forecast and the scenarios that show what breaks first.
- Placement per run, so inference goes where performance per dollar is best.
How it works
We measure the fleet.
Telemetry from every GPU node, joined with the bill, in 48 hours.
We forecast against real numbers.
Demand per model and endpoint, backtested, next to your team's assumptions.
You decide with a quote.
Buy, reserve, route or reclaim, each with the number that justifies it.
BEFORE YOU START
Before you start
Which GPUs and clouds?
Any GPU node the agent can see, in public cloud or private cloud. Read-only.
Do you touch the models or the prompts?
No. We measure execution and cost. Routing decisions are quotes your team applies.
Can this cut the bill without buying hardware?
It can. Idle GPU capacity and misrouted inference can both be recovered without a purchase.
Buy the GPU you need, not the one you fear.
Start with the assessment of your inference estate.